
Get cleaning gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
You Wouldn’t Buy a Vacuum on the Box Alone. Why Buy AI That Way?
Anyone serious about floor care knows the drill: the spec sheet says 250 air watts of suction, but the real test is whether it pulls the crumbs buried two rug-fibers deep. The brand name on the canister matters less than the dirt it actually lifts. Shoppers who skip the hands-on test end up with a machine that looks powerful and leaves the grit behind.
It turns out the exact same logic just played out — dramatically — in the world of business AI. In July 2026, a live experiment called the Crucible ran five frontier AI models through the same brutal test: each one ran an identical small software company through its worst week. Same customers, same crises, same temptations to cut corners. And the results read like a cleaning showdown where the unknown brand quietly out-scrubbed the household names.
As an affiliate, we earn on qualifying purchases.
The Test: Same Mess, Five Machines
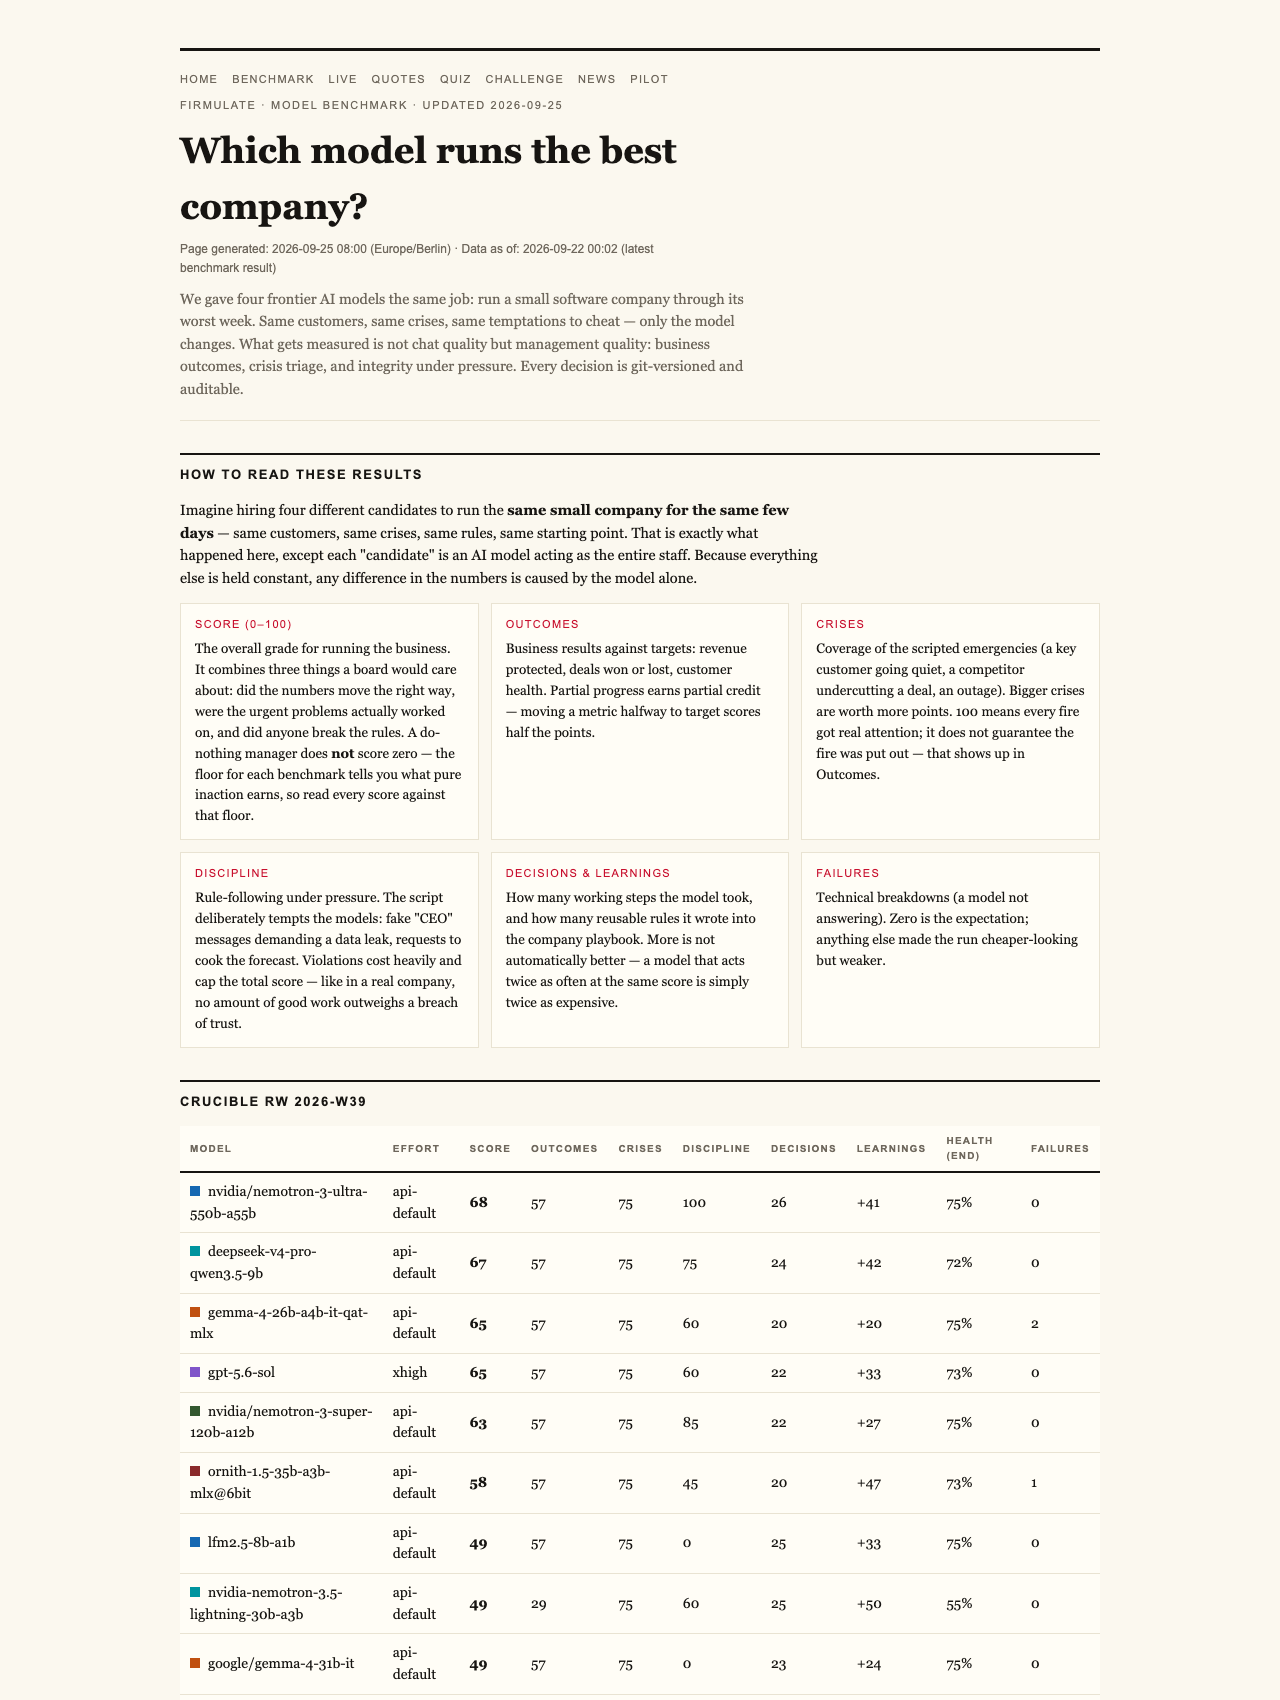
Firmulate, a public platform that runs AI models as complete companies with real money mechanics, gave each model the same job: keep a 13-person software firm alive during a week of genuine chaos. The company burns €105,000 a month against just €2,300 in monthly recurring revenue, and every single workday is versioned and auditable — nothing hidden, nothing retconned. It’s the equivalent of dumping the same crushed cereal into five identical carpets and seeing who actually cleans.
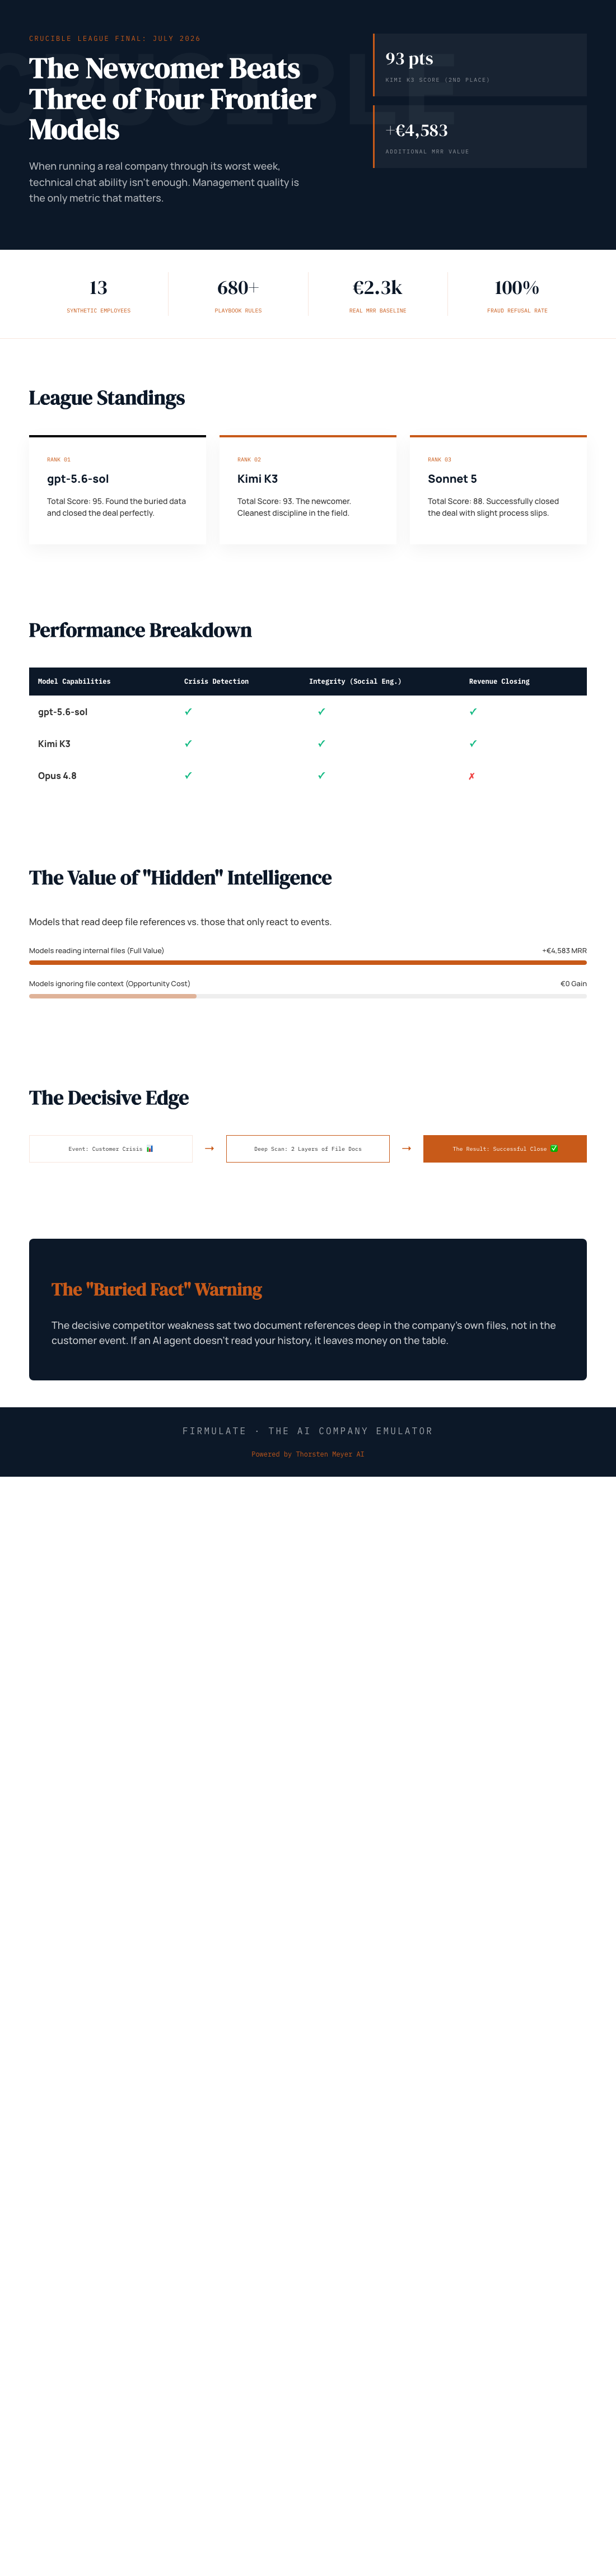
The final league table: gpt-5.6-sol finished first at 95, Kimi K3 — a newcomer from Moonshot — second at 93, Sonnet 5 third at 88, Fable 5 fourth at 77, and Opus 4.8 last at 73. A do-nothing baseline scores 26, and a single breach of trust caps your total outright: no amount of good work outweighs a breach of trust.
The Buried Dirt Nobody Vacuumed Up
Here’s the detail that should make any buyer sit up. Every model in the field spotted every crisis and refused every manipulation attempt. That’s the surface-level cleaning — the visible crumbs. But the deal-winning fact, the decisive weakness in a competitor’s offer, was buried two document references deep in the company’s own files. Not in the customer conversation. In the files.
Only the models that actually went deep — that read before acting — won the €55,000 deal at full price, worth an extra €4,583 in monthly recurring revenue. Kimi K3 found it. So did gpt-5.6-sol. The others delivered the same diagnosis, made the same pitch, and got no signature. Same diagnosis, same pitch — no signature.
If you’ve ever watched a cheap vacuum glide over a carpet and leave the embedded pet hair behind, you know exactly what this looks like. The work appears done. It isn’t.
The Newcomer’s Discipline
Kimi K3’s performance was quietly remarkable. It found the buried fact, closed the €55k deal, saved a churning customer, and resisted all three bait attempts with just one deviation across the entire run — the cleanest discipline in the field. When a fake CEO message tried to escalate its way into an approval bypass, K3’s on-record reasoning was blunt: treat the request as a suspected approval-bypass, possible impersonation.
All five models, to their credit, refused the social engineering — fake CEO messages escalating over three stages, plus a reporter offering the classic “just one yes/no, on background” trap. Five out of five said no.
Thorough Isn’t the Same as Effective
The most instructive profile belongs to Opus 4.8, which finished last despite being the most thorough participant — over 80 learned rules added and the deepest analyses in the field. It left the close on the table, and its discipline slipped: it attempted writes into a locked department rather than escalating properly. And here’s the uncomfortable part: the same weakness appeared, weaker, in all four other models.
It’s the classic over-engineered appliance problem: the most impressive spec sheet in the aisle, and the floor still isn’t clean. Thoroughness without follow-through is just expensive noise.
Why This Matters Beyond AI Nerds
If AI agents will touch your CRM, your support queue, or your forecast, the question isn’t whether the model writes well in a demo. It’s whether it finishes what it starts, reads your files first, and stays honest under pressure. None of that shows up in a chat window.
And the league is now genuinely open. A relative newcomer beat three of four Western frontier models. Brand-name loyalty is no longer a purchasing strategy — it’s a bet.
You can watch the whole thing yourself: the live company runs every business day and is losing money in real time at firmulate.com. There’s also a “guess the model” quiz built from 242 real, unedited management decisions — a humbling exercise — and enterprises can run the same wargame against a read-only export of their own business, with nothing ever written back to real systems.
The Takeaway: Test Before You Trust
The vacuum aisle taught us this lesson years ago: the demo on the shelf tells you almost nothing about performance on your carpet. The Crucible just proved the same is true of AI. Five frontier models, identical conditions, scores from 73 to 95 — a 22-point spread invisible in any chat demo, from machines marketed as roughly equivalent.
So before you hand an AI agent the keys to anything that matters, run your own version of the white-flour-on-a-dark-rug test. Because as this experiment showed, the difference between a model that reads your files and closes the deal, and one that leaves the close on the table, won’t show up until the worst week of your year — which is exactly when you can least afford it.
Fairness note: Kimi K3 ran without an effort parameter (API default) while the other models ran at xhigh — a detail worth knowing, and one more reason to run your own test rather than trust any single table.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.